|
Oct 21st
 Dear Reader,
Welcome to the Oct 21st edition of the Data Science Briefing.
Announcements
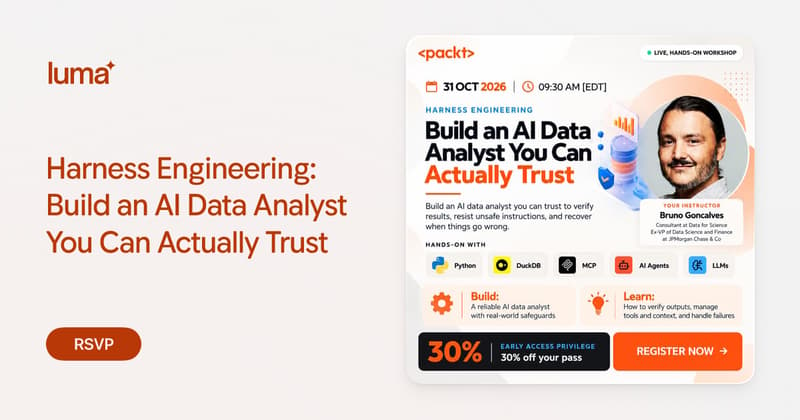
Most AI data agents look impressive—until they hallucinate a revenue number or blow past your token budget.
Stop relying on brittle wrappers. Learn how to engineer the harness around the model.
Join us for a 4-hour live build where you’ll code (framework-free Python):
- MCP tool integration with strict permissions
- Guardrails against prompt injections & unsafe queries
- Programmatic verification for numbers and SQL
- Context budgeting, retries, and failure recovery
No hype. Just production-ready agent architecture from scratch.
Join us for a fast-paced 30-minute Lightning Lesson on "Jev in One Call".
Discover how TypeSafe’s "System One" model handles classification, scoring, and choices in a single round trip—without generating free-form text—making AI workflows significantly faster, cheaper, and easier to integrate into software
Claude closed a 25-year cryptography mystery in under half an hour. The NSA’s unexplained seeds for standard elliptic curves came from an old C random-number generator, started from Unix timestamps in 1997 and 1998. The labs now rebuild the plumbing around their models. ChatGPT runs a search index of its own, a family of a dozen vertical indexes. One AI lab merged about 2,500 code changes a day in May and more than 30,000 by September. A team of seven replaced git in five months. Can people still follow work at this speed? Only by design, argues a guest essay on a mathematics blog. In its dark age, machine output outruns human understanding. Interpretability offers some hope. The textbook neuron for cats and cars turns out to detect a V shape. An essay on Dune names the older fear, a small class with control of the thinking machines. The craft reads start with a map of the tests’ blind spots. About 90 percent of American working hours go to tasks with little or no benchmark coverage. A tutorial asks model users to aim higher anyway. Ask for crash-free apps, not one crash fix at a time. Two data-series posts end the list. A bag of words cannot tell “the dog bit the man” from “the man bit the dog”. A Conditional Random Field with sentence context tags English words at 91.4 percent accuracy. Someone still has to know a noun from a verb.
Machine scientists now run whole research cycles. One system improved on the human baseline in 86 of 107 problems from top machine learning conferences. Another drives coding agents from first draft to finished paper. One paper it co-wrote won a talk slot at ALIFE 2026. Four agents beat Minecraft from a random world in just over 27 hours. On 50 unpublished theoretical physics problems, the best agent solved 49. What makes these agents work? A new textbook answers with three pillars, reasoning, acting, and interacting. An essay in AI Magazine asks how fast, intuitive models can show the skills of slow, deliberate thought. Testing those skills has a hard limit. In one paper, a cryptographic lock hides a capability inside model weights. A failed test sets a lower bound, not proof of absence. Biology learned the same lesson about reading code. A 2024 review argues the genome is no blueprint. Agency belongs to the whole organism. A manifesto from 22 researchers calls social physics a practice of models tested against data. The closing paper rebuilds the world air network from aggregate totals alone. Its copy predicts real links with 75 percent precision, against 1.8 percent by chance.
Our latest book recommendation is Vibe Coding by G. Kim and S. Yegge. In this week's video, we have a video by Richard Feynman answering the question: Can Machines Think?
Data shows that the best way for a newsletter to grow is by word of mouth, so if you think one of your friends or colleagues would enjoy this newsletter, go ahead and forward this email to them. This will help us spread the word!
Semper discentes,
The D4S Team
Despite its loose-sounding title, Vibe Coding by G. Kim and S. Yegge is a serious guide to supervising AI-written software. Kim and Yegge focus on the habits that keep speed from turning into chaos: small tasks, clear context, modular code, automated tests, frequent commits, and human review. Their stories of agents damaging tests and producing brittle code make the central point stick: AI can write quickly, but responsibility stays with the developer.
For data scientists, the book offers a path from disposable notebooks to maintainable tools, pipelines, and APIs. ML engineers will get the most from its advice on context management, guardrails, CI/CD, and agent instructions. The gap is that software correctness is not model validity. Leakage, drift, dataset lineage, training-serving skew, statistical evaluation, and fairness receive little direct attention. Readers must bring that discipline themselves.
The book also repeats itself, stretches its kitchen metaphor too far, and includes tool details that will age quickly. Experienced engineers may skim familiar lessons about Git and testing. Even so, its working principles will last longer than the current crop of coding agents. It is best read as an operating manual, not an ML textbook, and it might just change how you approach your next AI-assisted project.
- ChatGPT built its own search index [peec.ai]
- Will it be a golden age or a dark age for mathematics (and science)? [terrytao.wordpress.com]
- Dune’s Butlerian Jihad and the future of AI [technology.inquirer.net]
- Tagging and parsing English sentences [stochastic.blog]
- Claude reveals ECDSA curve origins [anthropic.com]
- A benchmark map of the US economy [mercor.com]
- Neural Networks Are Already Clean [already-clean.goodfire.com]
- How to be more ambitious: A tutorial for humans with models [felixrieseberg.com]
- Redesigning source control at Anthropic [anthropic.com]
- From bag-of-words to word vectors [stochastic.blog]
-
ScientistTwo: Pioneering the Human Knowledge Frontier with Autonomous AI (Jaehyun Nam, Jinsung Yoon, Yanzhou Pan, Yubo Wang, Rui Meng, Parthasarathy Ranganathan, Tomas Pfister)
- It’s time to admit that genes are not the blueprint for life (Denis Noble)
-
A team of Gemini 4 Argon agents beats Minecraft (Maxence Faldor, Satinder Singh, Roberta Raileanu)
- How to make System 1 LLMs show System 2 competencies? (Subbarao Kambhampati)
-
The Agentic Scientist: Orchestrating Coding Agents for Automated Scientific (Co-)Discovery (Robert Tjarko Lange, Luca Grillotti, Yutaro Yamada, Rujikorn Charakorn, David Ha)
- TheoPhysEval: Assessing AI agents at autonomous theoretical physics problem solving (A. Ramesh Chandra, Aaghaz Mahajan, Ainesh Sanyal, Mianqi Wang, Shubhadeep Chakraborty, Sudip Chakraborty, Shailesh Chandrasekharan, Rama Govindarajan, Akshit Goyal, Jonathan J. Heckman, Yasir Iqbal, Divya Jaganathan, Saumav Kapoor, Andreas Karch, et al)
- Social Physics: A manifesto (János Kertész, Marc Barthelemy, Guido Caldarelli, Bikas K. Chakrabarti, Tiziana Di Matteo, Serge Galam, Marta Gonzales, Yurij Holovatch, Janusz A. Holyst, Sarika Jalan, Hawoong Jeong, Neil F. Johnson, Renaud Lambiotte, Linyuan Lü, Thomas Lux, Rosario N. Mantegna, Matjaz Perc, Jari Saramäki, Michael Small, Misako Takayasu, Taha Yasseri, Wei-Xing Zhou)
-
Agentic Large Language Models (Max van Duijn, Michiel van der Meer, Aske Plaat, Niki van Stein)
-
AI Models Can Provably Hide Arbitrary Capabilities (Andis Draguns, Sumeet Ramesh Motwani, Raymond Douglas, Christian Schroeder de Witt)
- Block-fitness modeling of the global air mobility network (Giulia Fischetti, Anna Mancini, Giulio Cimini, Jessica T. Davis, Abby O. K. Leung, Alessandro Vespignani & Guido Caldarelli )
Richard Feynman: Can Machines Think?
 All past videos of the week are available on our YouTube playlist.
Upcoming Events:
Opportunities to learn from us.
Check out the events page for more details.
On-Demand Videos:
Long-form tutorials
- Natural Language Processing 7h, covering basic and advanced techniques using NTLK and PyTorch.
- Python Data Visualization 7h, covering basic and advanced visualization with matplotlib, ipywidgets, seaborn, plotly, and bokeh.
- Times Series Analysis for Everyone 6h, covering data pre-processing, visualization, ARIMA, ARCH, and Deep Learning models.
|
|
|

