|
Nov 13th
 Dear Reader,
Welcome to the Nov 13th edition of the Data Science Briefing.
Announcements
Every AI gives you an answer, but how many give you a confidence score you can actually trust?
If a model says it's 80% confident, is it actually right 80% of the time? In this free lesson recording, AI architect and physicist Bruno Gonçalves breaks down how to empirically verify AI reliability so you can safely run systems without a human in the loop.
Here is what you'll get out of it:
- Head-to-head calibration: Drawing reliability diagrams for Jev vs. Claude's self-reported confidence using 113 labeled tasks.
- Code that runs on Monday: Computing Expected Calibration Error (ECE) and Brier scores in just 10 lines of NumPy.
- Operationalizing probability: Setting clear workflow bands (auto, confirm, human) based on the real-world costs of false allows and false blocks.
Can You Trust Jev's scores?

But how does it actually compare to Claude?
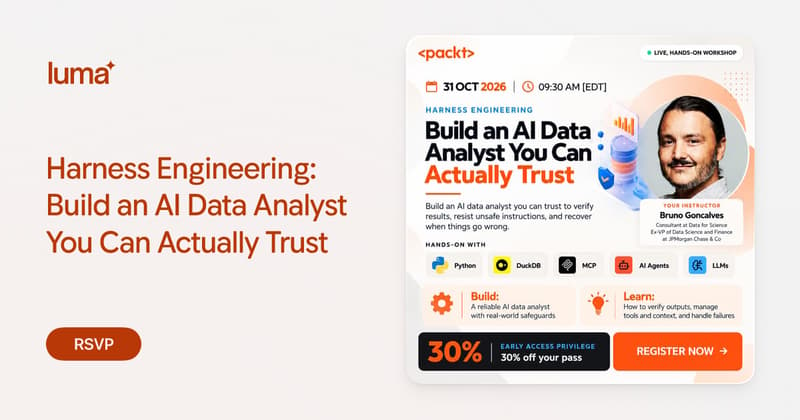
On November 18, I'm hosting a live, hands-on workshop where we'll put both models to the test, measuring accuracy, latency, and cost using real Python benchmarks.
Finding the right item is still the hard part. A new paper trains small networks once, offline, to route each query to its best match in a vector database. On 2.6 million passages, routing hits 95 percent recall in 1.74 milliseconds, against 3.36 for the standard method. The web faces the same problem from the reader’s side. Search engines once sent people out to the rest of the internet. Chatbots now answer in place. The column asks whether the open web survives that change. Agents need retrieval of their own, and an engineering post maps how agent memory works. In one game test, an older model wrote 413 files and earned one badge. A newer model kept 10 files and earned four. An offline pass called dreaming rereads old transcripts and fixes bad notes.
Reasoning looks more like search than logic. Each answer is one path through token space. Training raises the odds that some path lands on the right answer. The gains from longer thinking come from search done in training and stored in the weights. Image models walk a path from noise to structure. On 6,000 handwritten digits, a small flow beats a Gaussian baseline by 105.6 nats per image. A small diffusion model draws recognizable digits in 25 steps. An essay compares AI to the Homeric songs. It calls today’s agents “more than stochastic parrots and stranger than machine gods.” Freelance work is getting rebuilt from parts. In 43 of 63 categories, tasks common in chatbot use lost share of job postings, and rarer tasks gained. AI-related postings grew 45 percent more varied in task mix and carry bigger budgets.
Half the stack gets the same result with less work. A new clustering method matches 25 epochs of k-means in under 3. It sorted 10 billion image embeddings into 16 million clusters in 2.5 epochs. Zeroing fewer than 0.05 percent of a model’s weights matches full fine-tuning. The model forgets less than it does under full fine-tuning. A model that writes text in coarse-to-fine layers matches strong diffusion models at 10 to 31 times the speed. The rest is about fit. One paper searches for the best prompt for each model and task and lifts accuracy about 9 points on average. A personal health agent, built from 1,370 real health queries, splits its work among three specialists for data, medicine, and coaching. Detectors will keep missing slop, a new comment argues. Slop is a judgement a community makes, not a property of the text.
Our latest book recommendation is "Build with Claude Code" by T. Jo. In this week's video, we have an OpenAI Decisions API Full Tutorial for beginners.
Data shows that the best way for a newsletter to grow is by word of mouth, so if you think one of your friends or colleagues would enjoy this newsletter, go ahead and forward this email to them. This will help us spread the word!
Semper discentes,
The D4S Team
"Build with Claude Code" by T. Jo: 9 projects, 408 pages, and you write none of the code. You describe each program in plain English. Claude Code does all of the typing. The author, Taeho Jo, studies early Alzheimer’s diagnosis with deep learning at the Indiana University School of Medicine. Packt published this English edition of his Korean original on August 31, 2026. Each project is bigger than the last one. They run from a single webpage to a database-backed shopping list on Vercel and Supabase.
Why should a data scientist read a beginner’s book? The answer is deployment. Most of us stall at the notebook stage of a project. A model on a laptop serves no users at all. This book ends with a live app and a real database behind it. The middle chapters teach habits worth stealing for model work. Chapter 5 drills hallucination checks on generated quiz content. CLAUDE.md files carry project rules from one session to the next. Custom commands turn repeated chores into one-line calls. Chapter 6 covers API keys, .env files, and .gitignore entries. Chapter 7 scopes an app with the 5W1H questions. Sub-agents then build it in product, frontend, backend, and QA roles. Chapter 8 adds MCP servers, Skills, plugins, GitHub, and Playwright to the kit.
Model builders face two problems with this book. It assumes no programming background from its readers. Part 1 spends four chapters on AI history, prompt basics, installation, and a to-do app. An ML engineer will clear that half in an hour. The bigger gap sits in the machine learning content itself. Only one project builds a model, a handwriting recognizer on the MNIST digits. No chapter title mentions notebooks, data pipelines, evaluation, or model serving. Claude Code ships new releases most weeks. The printed screenshots will age within months. So skim Part 1 in a single evening. Give Part 2 a full weekend at the keyboard. Data scientists rarely lack models, only the plumbing around them. Your last model still sits on your laptop. After Chapter 8, point Claude Code at it.
- Faster Retrieval for Better, More Efficient RAG [machinelearning.apple.com]
- Work at the Frontier: AI’s effect on freelance work [openai.com]
- The Death Knell of Digital Search [newyorker.com]
- What objective is reasoning solving? [alexwang.ai]
- Flows and diffusion models on digits [stochastic.blog]
- The components of agent memory [www.anthropic.com]
- AI is a technological version of the Homeric songs [economist.com]
- AutoPDL: Automatic Prompt Optimization for LLM Agents (Claudio Spiess, Mandana Vaziri, Louis Mandel, Martin Hirzel)
- The anatomy of a personal health agent (A. Ali Heydari, Ken Gu, Vidya Srinivas, Hong Yu, Akshay Paruchuri, Zhihan Zhang, Yuwei Zhang, Qian He, Hamid Palangi, Nova Hammerquist, Ahmed A. Metwally, Brent Winslow, Yubin Kim, Kumar Ayush, Yuzhe Yang, Girish Narayanswamy, Maxwell A. Xu, Jake Garrison, Samuel Schmidgall, Amy Armento Lee, Jenny Vafeiadou, Ben Graef, Isaac R. Galatzer-Levy, Erik Schenck, Andrew Barakat, Javier Perez, Jacqueline Shreibati, John Hernandez, Anthony Z. Faranesh, Naghmeh Rezaei, Javier L. Prieto, Conor Heneghan, Jiening Zhan, Mark Malhotra, Shwetak Patel, Yun Liu, Tim Althoff, Xin Liu, Daniel McDuff, Xuhai Orson Xu)
- AI ‘slop’ is a social judgement (Richard Jean So, Hoyt Long, Cody Kommers, Mina Lee, Emily Wenger, Peter West, Eamon Duede, Ari Holtzman, Chenhao Tan)
- Next-Concept Modeling: Fast, Parallel Coarse-to-Fine Text Generation (Hermann Kumbong, Ishan S. Khare, Iddah Mlauzi, Andrew Woen, Charles Ding, E. Kelly Buchanan, Simran Arora, Azalia Mirhoseini, Christopher Ré)
- The Surprising Effectiveness of Deleting Weights in LLM Post-Training (Jack Lu, Zhenbang Yang, Mike Lasby, Tejas Pote, Yani Ioannou, Mengye Ren)
- e-means: outperforming k-means (in one-tenth the epochs) (Swann Bessa, Pierre-Emmanuel Mazaré, Gergely Szilvasy, Hugo Touvron, David Picard, Matthijs Douze, Hervé Jégou)
Decisions API Full Tutorial for Beginners
 All past videos of the week are available on our YouTube playlist.
Upcoming Events:
Opportunities to learn from us.
Check out the events page for more details.
On-Demand Videos:
Long-form tutorials
- Natural Language Processing 7h, covering basic and advanced techniques using NTLK and PyTorch.
- Python Data Visualization 7h, covering basic and advanced visualization with matplotlib, ipywidgets, seaborn, plotly, and bokeh.
- Times Series Analysis for Everyone 6h, covering data pre-processing, visualization, ARIMA, ARCH, and Deep Learning models.
|
|
|